Workflow Orchestration
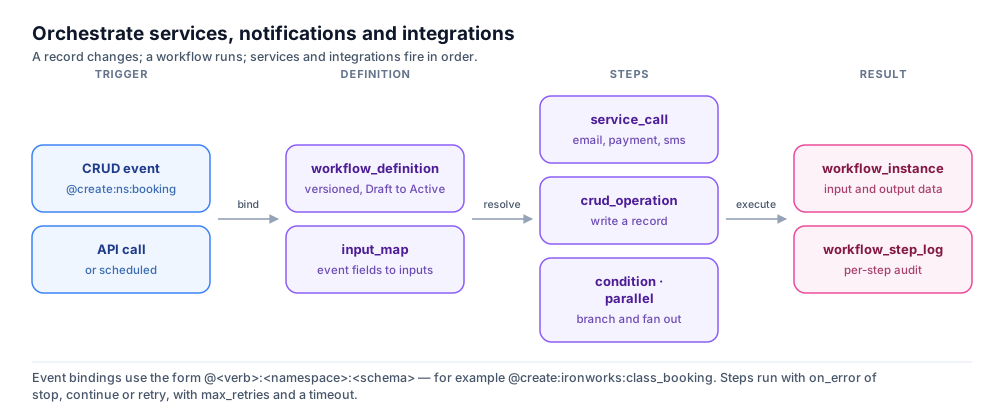
A record changes, a workflow runs, and services fire in a defined order — with the definition stored as an ordinary record and every step written to a log you can query.
What It Is For
The Shape
- •service_call — invoke an operation on an imported service. Carries service, operation and an input_map.
- •crud_operation — read or write a record. Carries operation, object_type, and data and/or record_uuid.
- •condition — the branching step type.
- •parallel — the fan-out step type.
- •transform — the value-shaping step type.
- •loop — repeat a body of sub-steps until a condition holds or a ceiling is reached. Carries steps, until and max_iterations.
{
  "name": "adverse_event_alert",
  "parent_type": "tenant",
  "workflow_id": "adverse_event_alert",
  "display_name": "Adverse Event Alert",
  "description": "Notify staff when a severe adverse event is logged",
  "version": "1.0.0",
  "enabled": true,
  "status": "Active",
  "on_error": "continue",

  "input_schema": {
    "event_uuid":  { "type": "string", "required": true },
    "event_name":  { "type": "string", "required": true },
    "severity":    { "type": "string", "required": true }
  },

  "steps": [
    {
      "id": "send_in_app_notification",
      "type": "service_call",
      "service": "notification",
      "operation": "send_notification",
      "input_map": {
        "title": "Severe Adverse Event: {{input.event_name}}",
        "body": "A new adverse event with severity {{input.severity}} has been reported."
      },
      "on_error": "continue"
    },
    {
      "id": "mark_processed",
      "type": "crud_operation",
      "operation": "update",
      "object_type": "trialhub:adverse_event",
      "record_uuid": "{{input.event_uuid}}",
      "data": {
        "workflow_status": "processed",
        "processed_at": "{{context.timestamp}}"
      }
    }
  ]
}How It Works
// event_bindings.json — shipped with the application bundle

[
  {
    "event": "@create:ironworks:class_booking",
    "workflow_id": "notify_on_booking",
    "input_map": {
      "booking_uuid": "uuid",
      "start_time":   "start_time"
    }
  },
  {
    "event": "@create:ironworks:order",
    "workflow_id": "notify_on_order",
    "input_map": {
      "order_uuid": "uuid",
      "order_name": "name"
    }
  }
]- 1
Define
Create the wf:workflow_definition record, with status Active and enabled true when you want it reachable.
- 2
Bind, or do not
Add an entry to event_bindings.json to fire it on a CRUD event. A workflow with no binding is still usable — it just has to be called.
- 3
Fire it directly when you need to
POST /api/v1/services/execute with service_id "workflows", operation "execute_workflow", and an input carrying the workflow_id. This works under an API key alone — which is what makes it reachable from a scheduled job or an external caller.
- 4
Observe the run
workflow_instance captures the run and workflow_step_log captures each step. Both are ordinary CRUD types in the wf namespace, queried with list-bulk like anything else.
POST /api/v1/services/execute

{
  "service_id": "workflows",
  "operation": "execute_workflow",
  "domain": "acme",
  "project_uuid": "9f3c1b6a-2e5d-4f81-b0a7-3c5e9d1f2a44",
  "input": {
    "workflow_id": "adverse_event_alert",
    "trigger_record_uuid": "3d7c9e11-5a24-4b8f-9e60-1c2a7b4d8e33"
  }
}
💡 The step log is the evidence
What You Get
- •A definition that is data. Version, list, update, disable or archive it through the ordinary CRUD API, with no deployment and no restart.
- •Per-step evidence. workflow_instance records the run and workflow_step_log records each step, so "did it fire?" is a query, not a log-scraping exercise.
- •Error policy at two levels: a workflow-wide on_error overridden per step, choosing stop, continue, retry or compensate, with max_retries, retry_delay_seconds and timeout_seconds.
- •Steps that cross the service boundary. A service_call reaches any imported integration; a crud_operation writes back through platform CRUD under the same authentication.
- •Value interpolation from the run context — {{input.event_name}}, {{context.timestamp}} — with no code between the binding and the step.
- •Event binding as configuration: a JSON entry, not a trigger you write and register.
- •Execution under an API key. The whole chain — execute, service_call into a plugin, crud_operation back into the platform — works with an X-API-Key and no user session.
- •Three trigger sources for one definition: api, crud_event and scheduled.
What You Decide
⚠️ A workflow is an executor, not a guarantee
- •Renewal. There is no automatic recurring billing and no dunning loop. If a subscription renews, you define renewal as a workflow — scheduled trigger, billing-date check, service_call to a payment integration — and you own the failure path when a charge declines. See Subscriptions & Memberships.
- •Capacity and contention. Capacity is a field to check against, not a lock the platform takes, and double-booking prevention is not guaranteed. A condition step can read a counter and refuse, but two bookings arriving together can both read the same value and both pass.
- •Idempotency. on_error: retry re-runs a step. If that step charges a card or sends an email, making it safe to run twice is your responsibility — the engine does not deduplicate.
On this page